LC output strength
Introduction
Question
Which postsynaptic partners of each LC type should be considered as meaningful connections.
Background
The axons of each LC type converge on a glomerulus, a discrete region of the central brain, and most glomeruli receive from one LC type alone.
While the dendrites of different LC neuron types are arranged in overlapping retinotopic arrays in the lobula, their synaptic termini in the central brain are grouped into discrete glomeruli, most of which receive input from a single LC neuron type
— Wu et al. 2016, p. 4 · PDF p. 4 · 10.7554/eLife.21022
If so, the outputs of one LC type should concentrate on a small set of partners, and the strength from the type to each partner (defined below) can show whether they do. Whether those partners sit near each other, as the partners of one glomerulus would, needs their positions and is left as an open question.
Dr. Chiappe suggested using the right hemisphere only, the better-proofread side, and focusing on LC10a, LC9, LC11, and LC16.
Proofread neurons vs fragments
Many postsynaptic sites sit on twigs, thin terminal branches, that never got attached to a neuron, and more proofreading gains little:
Substantial improvements in twig attachment are unobtainable with further proofreading, as increasing the postsynaptic attachment rate from 44.7% to 50% would require further proofreading of more than 700,000 fragments.
— Dorkenwald et al. 2024, p. 136 · PDF p. 136 · 10.1038/s41586-024-07558-y
So many of the segments that receive synapses from an LC cell are unproofread fragments. The main analysis counts proofread neurons as partners, and later figures show what changes when fragments are counted too, and when lateral partners are left out. This notebook defines a lateral connection as a connection onto any other LC cell, and a lateral partner is that LC cell.
Why threshold at all
analyses using the connectome should consider thresholding to remove spurious connections. Thresholds should be adjusted to the individual analyses.
— Dorkenwald et al. 2024, p. 126 · PDF p. 126 · 10.1038/s41586-024-07558-y
Dorkenwald also calls connections of more than nine synapses large and says the reconstruction finds nearly all of them:
We showed that the attachment rates of twigs is sufficient to facilitate detection of nearly all large connections (those with more than nine synapses).
— Dorkenwald et al. 2024, p. 135 · PDF p. 135 · 10.1038/s41586-024-07558-y
Dr. Chiappe suggested about ten synapses as the cutoff for a strong
connection, or wherever the distribution of weights shows a kink.
This notebook takes STRONG_SYN = 10 as a standard;
lc_output_strength_definitions
tests it against the distribution and asks what cutoff the data
themselves might suggest.
Expectations
The strong partners of a type, those with a strength of at least
STRONG_SYN (defined below), are a small fraction of its
partners but receive a large fraction of its output synapses.
Load data
The analysis reads census, which gives each cell's type,
sides, which says which hemisphere a cell is in,
proofread_ids, which lists the proofread neurons,
and connections.
connections has one row per connection, a pair of cells with at
least one synapse, as in the name of Codex's
connections_princeton_no_threshold table, with its weight and
the type of its presynaptic cell.
The table of every proofread neuron's connections is large,
so this notebook loads only the connections that start at the cells
it scores.
| root_id | primary_type |
|---|---|
| i64 | str |
| 720575940599457990 | "T4b" |
| 720575940599763910 | "T5b" |
| 720575940600623020 | "Dm3q" |
| 720575940602564320 | "KCg-m" |
| 720575940602720940 | "JO-CA" |
| … | … |
| 720575940661275009 | "KCab-p" |
| 720575940661281409 | "L4" |
| 720575940661285249 | "LPC2" |
| 720575940661304449 | "Lawf1" |
| 720575940661333889 | "CB2303" |
| root_id | side |
|---|---|
| i64 | str |
| 720575940596125868 | "right" |
| 720575940597856265 | "right" |
| 720575940597944841 | "right" |
| 720575940598267657 | "right" |
| 720575940599333574 | "right" |
| … | … |
| 720575940661323905 | "left" |
| 720575940661325697 | "left" |
| 720575940661327745 | "right" |
| 720575940661336193 | "left" |
| 720575940661339777 | "right" |
| root_id |
|---|
| i64 |
| 720575940599457990 |
| 720575940599763910 |
| 720575940600623020 |
| 720575940602309600 |
| 720575940602564320 |
| … |
| 720575940661275009 |
| 720575940661281409 |
| 720575940661285249 |
| 720575940661304449 |
| 720575940661333889 |
The types of interest are restricted to the right hemisphere.
cells = cells_of_types(census, sides, TYPES_OF_INTEREST)
pl.DataFrame(
    {
        "type": list(TYPES_OF_INTEREST),
        "right-hemisphere cells": [
            len(cells[_t]) for _t in TYPES_OF_INTEREST
        ],
    }
)
| type | right-hemisphere cells |
|---|---|
| str | i64 |
| "LC10a" | 121 |
| "LC9" | 92 |
| "LC11" | 61 |
| "LC16" | 74 |
connections is filtered while it loads to the connections whose
presynaptic cell is one of those cells.
with_pre_type (from helpers) labels each
with the type of its presynaptic cell, in the column pre_type.
A strength is taken over the cells of one type,
so the label says which connections belong together:
_scored = [_id for _ids in cells.values() for _id in _ids]
connections = with_pre_type(load_connections_of(_scored), cells)
connections
| pre_pt_root_id | post_pt_root_id | weight | pre_type |
|---|---|---|---|
| i64 | i64 | i64 | str |
| 720575940603578848 | 720575940381391499 | 1 | "LC11" |
| 720575940603578848 | 720575940381415307 | 1 | "LC11" |
| 720575940603578848 | 720575940381421195 | 1 | "LC11" |
| 720575940603578848 | 720575940381425291 | 1 | "LC11" |
| 720575940603578848 | 720575940381433227 | 1 | "LC11" |
| … | … | … | … |
| 720575940659229057 | 720575940649865718 | 1 | "LC11" |
| 720575940659229057 | 720575940650149753 | 2 | "LC11" |
| 720575940659229057 | 720575940651404278 | 2 | "LC11" |
| 720575940659229057 | 720575940653346038 | 2 | "LC11" |
| 720575940659229057 | 720575940661134465 | 1 | "LC11" |
Weight and strength
A weight belongs to a connection between two cells. Let \(w(i \to j)\) be the weight of the connection from cell \(i\) to cell \(j\), defined as the number of synapses \(i\) sends to \(j\). This notebook uses strength to describe the relationship between a type and one of its partners. For a type \(T\) and a partner \(j\), the strength from \(T\) to \(j\) is the weight of the heaviest single connection from a cell of \(T\) onto \(j\),
\(T\) is strongly connected to \(j\) when \(s(T \to j)\) is at or above
the cutoff STRONG_SYN,
that is, when some cell of \(T\) connects to \(j\) with at least that
many synapses.
Then \(j\) is a strong partner of \(T\).
Where the type is clear, \(s\) stands for \(s(T \to j)\).
The following example network will be used to illustrate some of the
analyses and methods in this notebook.
Its connections carry pre_type like the real ones.
example_cells = {"T": ["t1", "t2"], "U": ["u1"]}
example_connections = with_pre_type(
    pl.DataFrame(
        [
            ("t1", "j", 11),
            ("t2", "j", 5),
            ("u1", "j", 7),
            ("t1", "k", 6),
            ("t2", "k", 5),
            ("t1", "t2", 2),
            ("t2", "u1", 3),
        ],
        schema=["pre_pt_root_id", "post_pt_root_id", "weight"],
        orient="row",
    ),
    example_cells,
)
example_connections
| pre_pt_root_id | post_pt_root_id | weight | pre_type |
|---|---|---|---|
| str | str | i64 | str |
| "t1" | "j" | 11 | "T" |
| "t2" | "j" | 5 | "T" |
| "u1" | "j" | 7 | "U" |
| "t1" | "k" | 6 | "T" |
| "t2" | "k" | 5 | "T" |
| "t1" | "t2" | 2 | "T" |
| "t2" | "u1" | 3 | "T" |
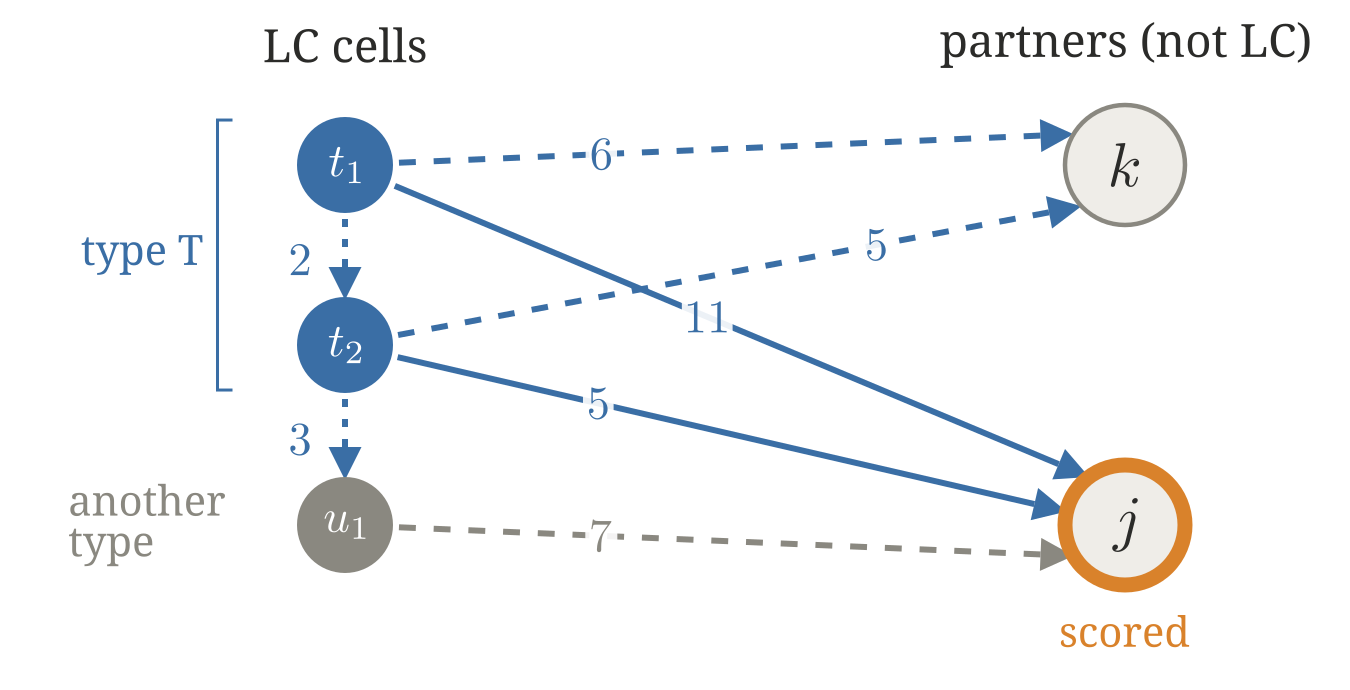
The solid arrows are the relevant connections \(w(i \to j)\) in the formula for \(s(T \to j)\); the largest weight among them is the strength.
strengths_to_partners groups the connections by type and partner.
For each pair it gives the strength s from the type to the
partner,
synapses, the total the cells of the type send to it,
and cells, the number of cells of the type that connect to it.
Connections whose presynaptic cell has no type are dropped.
def strengths_to_partners(
    connections: pl.DataFrame, *, by: str = "pre_type"
) -> pl.DataFrame:
    """The strength from each group of presynaptic cells to each of its
    partners.

    by names the column that labels the group of each connection's
    presynaptic cell, usually the type; a strength is taken over the
    cells that share a label.
    DataFrame[by, partner, s, synapses, cells]: s is the largest weight
    onto the partner, synapses the sum of weights, and cells the number
    of presynaptic cells that connect to it.
    """
    return (
        connections.drop_nulls(by)
        .group_by(by, "post_pt_root_id")
        .agg(
            s=pl.col("weight").max(),
            synapses=pl.col("weight").sum(),
            cells=pl.len(),
        )
        .rename({"post_pt_root_id": "partner"})
        .sort(by, "partner")
    )
| pre_type | partner | s | synapses | cells |
|---|---|---|---|---|
| str | str | i64 | i64 | u32 |
| "T" | "j" | 11 | 16 | 2 |
| "T" | "k" | 6 | 11 | 2 |
| "T" | "t2" | 2 | 2 | 1 |
| "T" | "u1" | 3 | 3 | 1 |
| "U" | "j" | 7 | 7 | 1 |
At STRONG_SYN = 10, \(T\) is strongly connected to \(j\) because one connection, from \(t_1\), is already above it (the strength is 11). \(T\) is not strongly connected to \(k\): the strength from \(T\) to \(k\) is 6, though 2 cells of \(T\) send it 11 synapses in total and none alone reaches the cutoff.
On the real data, the strengths from LC10a to its partners:
strengths_10a = strengths_to_partners(connections).filter(
    pl.col("pre_type") == "LC10a"
)
strengths_10a
| pre_type | partner | s | synapses | cells |
|---|---|---|---|---|
| str | i64 | i64 | i64 | u32 |
| "LC10a" | 720575940379710175 | 1 | 1 | 1 |
| "LC10a" | 720575940379714527 | 1 | 1 | 1 |
| "LC10a" | 720575940379724716 | 1 | 1 | 1 |
| "LC10a" | 720575940379730143 | 1 | 1 | 1 |
| "LC10a" | 720575940379737004 | 1 | 1 | 1 |
| … | … | … | … | … |
| "LC10a" | 720575940659507329 | 2 | 2 | 1 |
| "LC10a" | 720575940660340353 | 1 | 1 | 1 |
| "LC10a" | 720575940660758401 | 1 | 1 | 1 |
| "LC10a" | 720575940661134465 | 1 | 1 | 1 |
| "LC10a" | 720575940661205633 | 1 | 1 | 1 |
The strong partners of a type are those with \(s\) at or above the
cutoff.
strong_partners returns their ids
def strong_partners(
    partners: pl.DataFrame, cutoff: int = STRONG_SYN
) -> set[int]:
    """Root ids of the partners whose s is at or above cutoff.

    partners is DataFrame[partner, s, ...], as strengths_to_partners
    returns it.
    """
    return set(partners.filter(pl.col("s") >= cutoff)["partner"].to_list())
{720575940629900816, 720575940635052569, 720575940624579100, 720575940630310431, 720575940606337056, 720575940647291427, 720575940629853739, 720575940630780463, 720575940617859121, 720575940617019442, 720575940617922097, 720575940618128433, 720575940639702581, 720575940644941876, 720575940629856312, 720575940619159105, 720575940629883971, 720575940631517251, 720575940627491914, 720575940627808847, 720575940618139221, 720575940631938647, 720575940638642776, 720575940622105182, 720575940633471583, 720575940622240355, 720575940619169901, 720575940637846643, 720575940620444788, 720575940620836988, 720575940628227198, 720575940606099586, 720575940637464718, 720575940635014807, 720575940627758744, 720575940629669531, 720575940616169117, 720575940616169629, 720575940652922529, 720575940630826660, 720575940622029990, 720575940627094696, 720575940590678187, 720575940608342706, 720575940623263415, 720575940618467513, 720575940627249850, 720575940615193787, 720575940627282618, 720575940638271677, 720575940634743999, 720575940621779661, 720575940616888020, 720575940628916444, 720575940616434911, 720575940632125154, 720575940612752611, 720575940618578150, 720575940628782824, 720575940621701358, 720575940624838899, 720575940650455286, 720575940621925631, 720575940623004933, 720575940623016709, 720575940623318280, 720575940607125771, 720575940620802836, 720575940622538520, 720575940625500956, 720575940616012061, 720575940617520413, 720575940645579556, 720575940624962341, 720575940622365991, 720575940612227880, 720575940632330538, 720575940630812473, 720575940636249407, 720575940636302143, 720575940620362049, 720575940613502786, 720575940624335689, 720575940640425294, 720575940633007953, 720575940626039129, 720575940639031642, 720575940625440100, 720575940637536101, 720575940632745320, 720575940634356587, 720575940620326253, 720575940643949934, 720575940646350702, 720575940610389873, 720575940611802994, 720575940638668659, 720575940620174708, 720575940609909112, 720575940627693437, 720575940635263383, 720575940610903961, 720575940632409500, 720575940619714974, 720575940619453861, 720575940621680041, 720575940611623859, 720575940636589492, 720575940623107509, 720575940618510265, 720575940604732350, 720575940630160325, 720575940614190022, 720575940611694034, 720575940618021332, 720575940608269782, 720575940623541718, 720575940620146141, 720575940614387683, 720575940615834086, 720575940628936168, 720575940622480372, 720575940633686520, 720575940624175615}
Who the partners are
strengths_to_partners_with_cell_fraction is
strengths_to_partners with one more column,
cell_fraction, the fraction of the type's cells that connect to
the partner, and pre_type renamed type:
def strengths_to_partners_with_cell_fraction(
    connections: pl.DataFrame, cells_by_type: dict[str, list]
) -> pl.DataFrame:
    """The strength of every partner of each type.

    connections carry pre_type, as with_pre_type adds it from
    cells_by_type, which maps a type name to the ids of its cells; its
    sizes are the denominators of cell_fraction, so a cell with no
    connection still counts.
    DataFrame[type, partner, s, synapses, cells, cell_fraction].
    """
    size = {name: len(ids) for name, ids in cells_by_type.items()}
    return (
        strengths_to_partners(connections)
        .rename({"pre_type": "type"})
        .with_columns(
            cell_fraction=pl.col("cells") / pl.col("type").replace_strict(size)
        )
    )
| type | partner | s | synapses | cells | cell_fraction |
|---|---|---|---|---|---|
| str | str | i64 | i64 | u32 | f64 |
| "T" | "j" | 11 | 16 | 2 | 1.0 |
| "T" | "k" | 6 | 11 | 2 | 1.0 |
| "T" | "t2" | 2 | 2 | 1 | 0.5 |
| "T" | "u1" | 3 | 3 | 1 | 0.5 |
| "U" | "j" | 7 | 7 | 1 | 1.0 |
label_partners adds three labels to a table of partners:
whether the partner is a proofread neuron (proofread),
its own cell type (partner_type),
which is the census type for a typed neuron,
untyped neuron for a proofread neuron the census does not name,
and unproofread fragment for everything else,
and whether it is an LC cell itself (lateral).
On the real partners of the types of interest, with strong added
for the partners whose \(s\) is at or above STRONG_SYN:
def label_partners(
    partners: pl.DataFrame,
    census: pl.DataFrame,
    proofread_ids: pl.DataFrame,
) -> pl.DataFrame:
    """partners with the columns partner_type, proofread, and lateral.

    partners is DataFrame[partner, ...]; census gives each cell's
    primary_type by root_id, and proofread_ids lists the proofread
    root_id values.
    """
    census_types = census.select(
        partner=pl.col("root_id"), partner_type=pl.col("primary_type")
    )
    return (
        partners.join(census_types, on="partner", how="left")
        .with_columns(
            proofread=pl.col("partner").is_in(
                proofread_ids["root_id"].to_list()
            )
        )
        .with_columns(
            partner_type=pl.coalesce(
                "partner_type",
                pl.when("proofread")
                .then(pl.lit("untyped neuron"))
                .otherwise(pl.lit("unproofread fragment")),
            )
        )
        .with_columns(lateral=pl.col("partner_type").str.contains(r"^LC\d"))
    )
def partner_populations(partners: pl.DataFrame) -> dict[str, pl.DataFrame]:
    """The partners under the four ways of choosing them that the
    figures compare: "proofread", "proofread, no lateral", "with
    fragments", and "with fragments, no lateral"."""
    proofread = partners.filter(pl.col("proofread"))
    return {
        "proofread": proofread,
        "proofread, no lateral": proofread.filter(~pl.col("lateral")),
        "with fragments": partners,
        "with fragments, no lateral": partners.filter(~pl.col("lateral")),
    }
partners = label_partners(
    strengths_to_partners_with_cell_fraction(connections, cells),
    census,
    proofread_ids,
).with_columns(strong=pl.col("s") >= STRONG_SYN)
proofread_partners = partners.filter(pl.col("proofread"))
populations = partner_populations(partners)
partners
| type | partner | s | synapses | cells | cell_fraction | partner_type | proofread | lateral | strong |
|---|---|---|---|---|---|---|---|---|---|
| str | i64 | i64 | i64 | u32 | f64 | str | bool | bool | bool |
| "LC10a" | 720575940379710175 | 1 | 1 | 1 | 0.008264 | "unproofread fragment" | false | false | false |
| "LC10a" | 720575940379714527 | 1 | 1 | 1 | 0.008264 | "unproofread fragment" | false | false | false |
| "LC10a" | 720575940379724716 | 1 | 1 | 1 | 0.008264 | "unproofread fragment" | false | false | false |
| "LC10a" | 720575940379730143 | 1 | 1 | 1 | 0.008264 | "unproofread fragment" | false | false | false |
| "LC10a" | 720575940379737004 | 1 | 1 | 1 | 0.008264 | "unproofread fragment" | false | false | false |
| … | … | … | … | … | … | … | … | … | … |
| "LC9" | 720575940660758401 | 1 | 1 | 1 | 0.01087 | "Li08" | true | false | false |
| "LC9" | 720575940661134465 | 2 | 4 | 3 | 0.032609 | "Li06" | true | false | false |
| "LC9" | 720575940661244033 | 2 | 2 | 1 | 0.01087 | "TmY15" | true | false | false |
| "LC9" | 720575940661318017 | 2 | 5 | 3 | 0.032609 | "LLPC3" | true | false | false |
| "LC9" | 720575940661327745 | 1 | 1 | 1 | 0.01087 | "LTe09" | true | false | false |
Most partners are fragments. Their connections are weak, but there are so many of them that they receive a large share of each type's output synapses. The bars show the percent of a type's partners (top) and of its output synapses (bottom) that are proofread neurons.
status_fraction = (
    partners.group_by("type")
    .agg(
        proofread_partners=pl.col("proofread").mean(),
        proofread_synapses=pl.col("synapses")
        .filter(pl.col("proofread"))
        .sum()
        / pl.col("synapses").sum(),
    )
    .sort("type")
)
_long = status_fraction.unpivot(
    index="type", variable_name="measure", value_name="share"
).with_columns(
    measure=pl.col("measure").replace(
        {
            "proofread_partners": "partners",
            "proofread_synapses": "output synapses",
        }
    )
)
_bars = alt.Chart(_long).encode(
    y=alt.Y("type:N", sort=list(TYPES_OF_INTEREST), title=None),
    x=alt.X(
        "share:Q",
        scale=alt.Scale(domain=[0, 1]),
        axis=alt.Axis(format="%"),
        title="% proofread",
    ),
)
alt.layer(
    _bars.mark_bar().encode(
        color=type_color(),
        tooltip=[
            "type:N",
            "measure:N",
            alt.Tooltip("share:Q", format=".0%"),
        ],
    ),
    _bars.mark_text(align="left", dx=4).encode(
        text=alt.Text("share:Q", format=".0%")
    ),
).properties(width=420, height=80).facet(
    row=alt.Row(
        "measure:N", title=None, sort=["partners", "output synapses"]
    )
)
Proofread neurons are 8% (LC10a) to 13% (LC16) of a type's partners and receive 49% (LC11) to 53% (LC10a) of its output synapses. At most 8 proofread partners of a type have no census type, so the two labels nearly coincide.
Strengths from each type to its proofread partners
From here to the strong-set figure, partners are the proofread neurons. The table gives the scale of the data: how many partners each type has, how strong the typical one is, and how many are strong. The last three columns count the unproofread fragments that would add to the strong set, the proofread partners that are LC cells, and how many of those are strong.
partner_counts = partners.group_by("type", maintain_order=True).agg(
    pl.col("proofread").sum().alias("proofread partners"),
    pl.col("s").filter(pl.col("proofread")).median().alias("median s"),
    pl.col("s").filter(pl.col("proofread")).max().alias("max s"),
    (pl.col("strong") & pl.col("proofread")).sum().alias("strong"),
    (pl.col("strong") & ~pl.col("proofread"))
    .sum()
    .alias("strong fragments"),
    (pl.col("lateral") & pl.col("proofread"))
    .sum()
    .alias("proofread LC partners"),
    (pl.col("strong") & pl.col("lateral") & pl.col("proofread"))
    .sum()
    .alias("strong LC partners"),
)
partner_counts
| type | proofread partners | median s | max s | strong | strong fragments | proofread LC partners | strong LC partners |
|---|---|---|---|---|---|---|---|
| str | u32 | f64 | i64 | u32 | u32 | u32 | u32 |
| "LC10a" | 2634 | 1.0 | 93 | 122 | 2 | 876 | 37 |
| "LC11" | 4231 | 1.0 | 85 | 326 | 0 | 1076 | 194 |
| "LC16" | 2856 | 1.0 | 67 | 37 | 0 | 714 | 2 |
| "LC9" | 3908 | 1.0 | 91 | 331 | 10 | 1139 | 242 |
How many partners sit at each strength
strengths_by_type collects the values of one column for each
type, here \(s\) of the proofread partners.
The bins follow BIN_EDGES, so the strong set (dark bars) starts
at a bin edge.
On a linear axis the first bin swallows everything,
so the counts are on a log axis; read a bar's height on it as an
order of magnitude.
def strengths_by_type(
    partners: pl.DataFrame,
    column: str,
    types: Sequence[str] = TYPES_OF_INTEREST,
) -> dict[str, pl.Series]:
    """The values of column among the partners of each type, as
    {type: Series}; partners has the column type."""
    return {t: partners.filter(pl.col("type") == t)[column] for t in types}
_labels = [
    str(_a) if _b - _a == 1 else f"{_a}-{_b - 1}"
    for _a, _b in pairwise(BIN_EDGES)
] + [f"≥{BIN_EDGES[-1]}"]
_rows = []
for _t, _strength in strengths_by_type(proofread_partners, "s").items():
    _counts = np.bincount(
        np.digitize(_strength, BIN_EDGES) - 1, minlength=len(BIN_EDGES)
    )
    _rows += [
        {
            "type": _t,
            "strength": _label,
            "partners": int(_n),
            "strong": _lower >= STRONG_SYN,
        }
        for _label, _lower, _n in zip(
            _labels, BIN_EDGES, _counts, strict=True
        )
        if _n > 0
    ]
_shared = alt.Chart(pl.DataFrame(_rows)).encode(
    x=alt.X(
        "strength:N",
        sort=_labels,
        title="s (synapses)",
        axis=alt.Axis(labelAngle=0),
    ),
    y=alt.Y(
        "partners:Q",
        scale=alt.Scale(type="log", domain=[1, 10000]),
        axis=alt.Axis(values=[1, 10, 100, 1000, 10000], format=","),
        title="partners (log scale)",
    ),
)
_bars = _shared.mark_bar().encode(
    y2=alt.Y2(datum=1),
    color=type_color(),
    opacity=alt.condition("datum.strong", alt.value(1.0), alt.value(0.4)),
    tooltip=[
        "type:N",
        "strength:N",
        alt.Tooltip("partners:Q", format=","),
    ],
)
_counts = _shared.mark_text(dy=-7).encode(
    text=alt.Text("partners:Q", format=",")
)
alt.layer(_bars, _counts).properties(width=290, height=150).facet(
    facet=alt.Facet("type:N", sort=list(TYPES_OF_INTEREST), title=None),
    columns=2,
)
How much the strong set carries
The strong set of a type is its strong partners,
those with \(s \ge\) STRONG_SYN.
The claim to check is that this set is a small fraction of the
partners but receives a large fraction of the output synapses.
strong_share counts the strong partners of each type and gives the
two fractions,
here for each choice of partners:
def strong_share(
    partners: pl.DataFrame, *, cutoff: int = STRONG_SYN
) -> pl.DataFrame:
    """How much of each type's partners and output the strong set is.

    partners is DataFrame[type, s, synapses, ...].
    DataFrame[type, n_partners, n_strong, partner_fraction,
    synapse_fraction]: the fractions are of the partners and of the
    output synapses that go to partners, for those with s at or above
    cutoff.
    """
    strong = pl.col("s") >= cutoff
    return (
        partners.group_by("type", maintain_order=True)
        .agg(
            n_partners=pl.len(),
            n_strong=strong.sum(),
            synapse_fraction=pl.col("synapses").filter(strong).sum()
            / pl.col("synapses").sum(),
        )
        .with_columns(
            partner_fraction=pl.col("n_strong") / pl.col("n_partners")
        )
        .select(
            "type",
            "n_partners",
            "n_strong",
            "partner_fraction",
            "synapse_fraction",
        )
    )
concentration = pl.concat(
    [
        strong_share(_frame).with_columns(population=pl.lit(_name))
        for _name, _frame in populations.items()
    ]
)
concentration
| type | n_partners | n_strong | partner_fraction | synapse_fraction | population |
|---|---|---|---|---|---|
| str | u32 | u32 | f64 | f64 | str |
| "LC10a" | 2634 | 122 | 0.046317 | 0.734084 | "proofread" |
| "LC11" | 4231 | 326 | 0.07705 | 0.626887 | "proofread" |
| "LC16" | 2856 | 37 | 0.012955 | 0.529441 | "proofread" |
| "LC9" | 3908 | 331 | 0.084698 | 0.726901 | "proofread" |
| "LC10a" | 1758 | 85 | 0.04835 | 0.852108 | "proofread, no lateral" |
| … | … | … | … | … | … |
| "LC9" | 43766 | 341 | 0.007791 | 0.368397 | "with fragments" |
| "LC10a" | 33312 | 87 | 0.002612 | 0.408004 | "with fragments, no lateral" |
| "LC11" | 49317 | 132 | 0.002677 | 0.305561 | "with fragments, no lateral" |
| "LC16" | 22076 | 35 | 0.001585 | 0.294033 | "with fragments, no lateral" |
| "LC9" | 42627 | 99 | 0.002322 | 0.311139 | "with fragments, no lateral" |
To see both fractions at once, rank a type's partners by \(s\), strongest first, and draw the fraction of the type's synapses received by the top \(k\) partners against \(k\) as a fraction of all partners. A type that spread its output evenly would follow the dotted line; the dot on each curve is where the strong set ends.
# Wider than the default to leave room for the legend beside the
# axes.
_fig, _ax = plt.subplots(figsize=(9, 5))
for _t in TYPES_OF_INTEREST:
    for _label, _style in (("proofread", "-"), ("with fragments", "--")):
        _frame = populations[_label]
        _p = _frame.filter(pl.col("type") == _t).sort(
            ["s", "synapses"], descending=True
        )
        _k = int((_p["s"] >= STRONG_SYN).sum())
        _cum = (_p["synapses"].cum_sum() / _p["synapses"].sum()).to_numpy()
        _x = np.arange(1, _p.height + 1) / _p.height
        _faded = _label != "proofread"
        _ax.plot(
            _x,
            _cum,
            linestyle=_style,
            color=TYPE_COLORS[_t],
            alpha=FADED_ALPHA + 0.25 if _faded else 1.0,
        )
        _ax.plot(
            _x[_k - 1],
            _cum[_k - 1],
            "o",
            color=TYPE_COLORS[_t],
            markerfacecolor="white" if _faded else TYPE_COLORS[_t],
        )
_ax.plot([0, 1], [0, 1], color=CONTEXT_COLOR, linestyle=":")
_ax.set_xlim(-0.02, 1.02)
_ax.set_ylim(-0.02, 1.02)
_ax.xaxis.set_major_formatter(PercentFormatter(1.0))
_ax.yaxis.set_major_formatter(PercentFormatter(1.0))
_ax.set_xlabel(r"top partners by $s$, % of all partners")
_ax.set_ylabel("% of the type's output synapses")
_proofread = concentration.filter(pl.col("population") == "proofread")
_fig.legend(
    handles=[
        Line2D(
            [],
            [],
            color=TYPE_COLORS[_r["type"]],
            marker="o",
            label=f"{_r['type']}: {_r['partner_fraction']:.1%} of "
            f"partners, {_r['synapse_fraction']:.0%} of synapses",
        )
        for _r in _proofread.iter_rows(named=True)
    ]
    + [
        Line2D(
            [],
            [],
            color=CONTEXT_COLOR,
            linestyle="--",
            marker="o",
            markerfacecolor="white",
            label="with fragments",
        ),
        Line2D(
            [],
            [],
            color=CONTEXT_COLOR,
            linestyle=":",
            label="all partners equal",
        ),
    ],
    loc="outside center right",
)
_fig
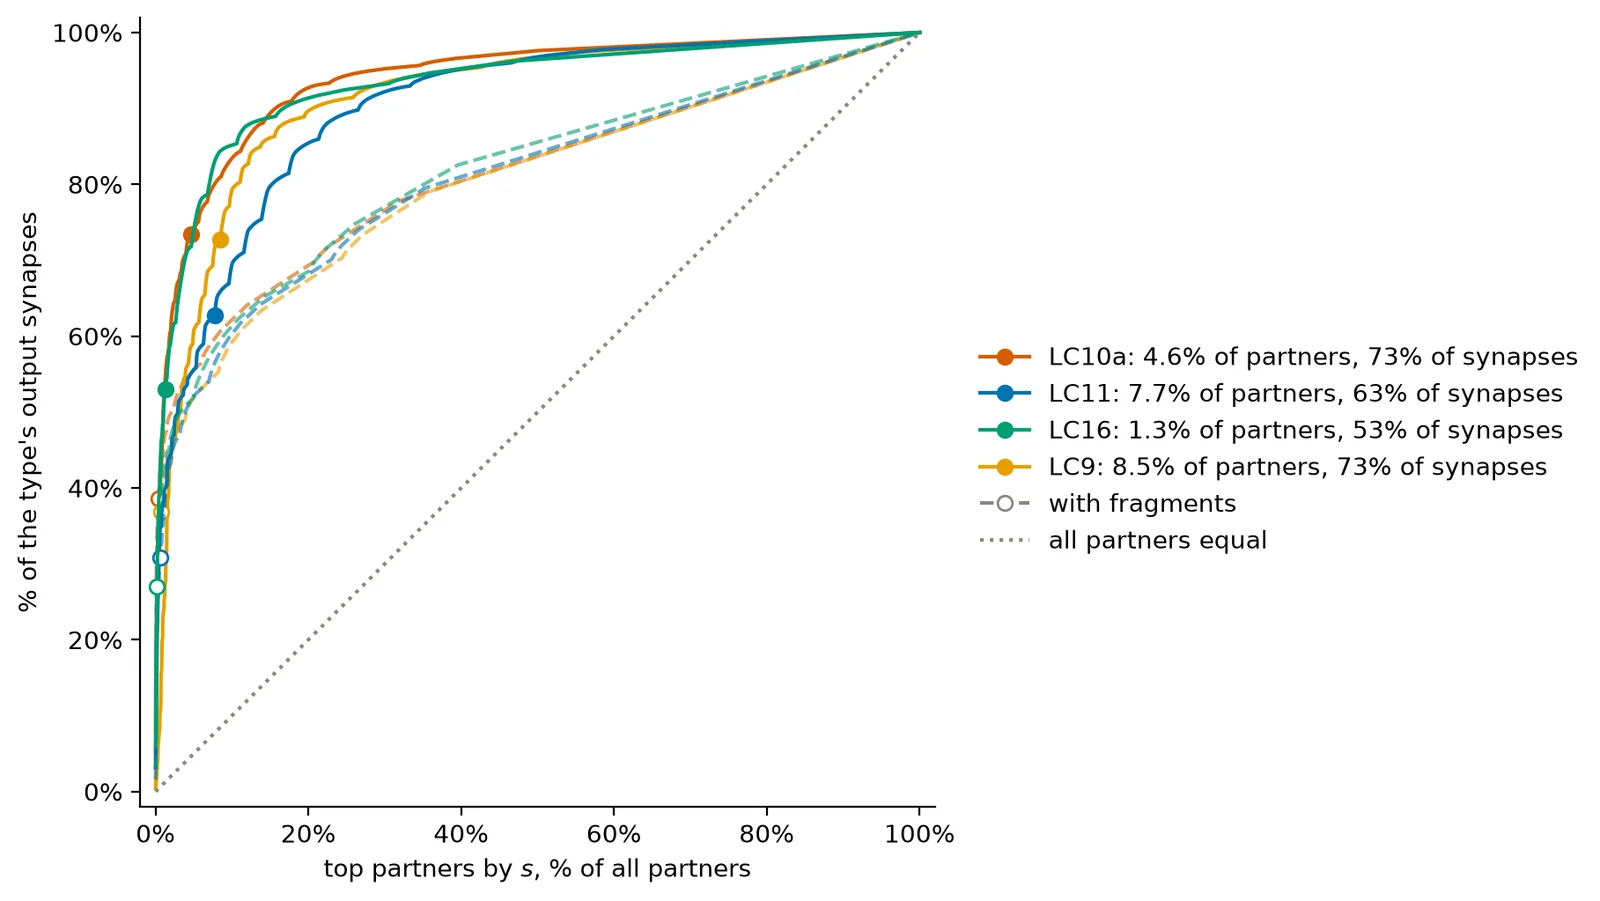
Among the proofread partners the strong set is 1.3% (LC16) to 8.5% (LC9) of a type's partners and receives 53% (LC16) to 73% (LC10a) of the output synapses that go to proofread partners. Counting fragments as partners, it is 0.2% (LC16) to 0.8% (LC9) of partners and 27% (LC16) to 39% (LC10a) of all output synapses.
Lateral connections
So far the partners include LC cells. A connection from one LC cell onto another is lateral: it does not carry the output of the type to the rest of the brain. The bars split each type's strong proofread partners into LC cells and other cells.
lateral_split = (
    proofread_partners.filter(pl.col("strong"))
    .group_by("type", "lateral")
    .agg(partners=pl.len())
    .with_columns(
        kind=pl.when(pl.col("lateral"))
        .then(pl.lit("LC cells (lateral)"))
        .otherwise(pl.lit("other cells"))
    )
)
alt.Chart(lateral_split).mark_bar().encode(
    y=alt.Y("type:N", sort=list(TYPES_OF_INTEREST), title=None),
    x=alt.X("partners:Q", title="strong proofread partners"),
    color=type_color(),
    opacity=alt.Opacity(
        "kind:N",
        scale=alt.Scale(
            domain=["other cells", "LC cells (lateral)"],
            range=[1.0, FADED_ALPHA],
        ),
        title=None,
    ),
    order=alt.Order("lateral:N"),
    tooltip=["type:N", "kind:N", "partners:Q"],
).properties(width=420, height=140)
Strong proofread partners that are LC cells, of all strong proofread partners: LC10a: 37 of 122, LC9: 242 of 331, LC11: 194 of 326, LC16: 2 of 37.
The types of those LC cells, for each type:
lateral_types = (
    proofread_partners.filter(pl.col("strong") & pl.col("lateral"))
    .group_by("type", "partner_type")
    .agg(partners=pl.len())
    .sort("type", "partners", descending=[False, True])
)
lateral_types
| type | partner_type | partners |
|---|---|---|
| str | str | u32 |
| "LC10a" | "LC10a" | 19 |
| "LC10a" | "LC10d" | 12 |
| "LC10a" | "LC14a1" | 5 |
| "LC10a" | "LC9" | 1 |
| "LC11" | "LC17" | 107 |
| … | … | … |
| "LC9" | "LC14a1" | 15 |
| "LC9" | "LC13" | 2 |
| "LC9" | "LC31c" | 1 |
| "LC9" | "LC31a" | 1 |
| "LC9" | "LC36" | 1 |
The strong set
The strong set is what downstream notebooks take from this one:
the partners that are proofread neurons,
with a strength of at least STRONG_SYN,
and with the LC cells removed from them afterwards,
since a lateral partner is a neighbor of the type and not a target
of its output.
strong_set returns those rows of partners:
def strong_set(
    partners: pl.DataFrame, *, cutoff: int = STRONG_SYN
) -> pl.DataFrame:
    """The rows of partners that are proofread neurons, not LC cells,
    with s at or above cutoff.

    partners is DataFrame[s, proofread, lateral, ...], as label_partners
    returns it.
    """
    return partners.filter(
        pl.col("proofread") & ~pl.col("lateral") & (pl.col("s") >= cutoff)
    )
| type | partner | s | synapses | cells | cell_fraction | partner_type | proofread | lateral | strong |
|---|---|---|---|---|---|---|---|---|---|
| str | i64 | i64 | i64 | u32 | f64 | str | bool | bool | bool |
| "LC10a" | 720575940604732350 | 11 | 74 | 24 | 0.198347 | "CB1294" | true | false | true |
| "LC10a" | 720575940607125771 | 17 | 357 | 71 | 0.586777 | "CB3127" | true | false | true |
| "LC10a" | 720575940608342706 | 13 | 153 | 39 | 0.322314 | "AOTU008c" | true | false | true |
| "LC10a" | 720575940610389873 | 48 | 663 | 50 | 0.413223 | "AOTU027" | true | false | true |
| "LC10a" | 720575940610903961 | 19 | 282 | 36 | 0.297521 | "CB2070" | true | false | true |
| … | … | … | … | … | … | … | … | … | … |
| "LC9" | 720575940641706184 | 21 | 365 | 66 | 0.717391 | "PVLP138" | true | false | true |
| "LC9" | 720575940644465568 | 13 | 180 | 46 | 0.5 | "LTe20" | true | false | true |
| "LC9" | 720575940644775534 | 33 | 1547 | 92 | 1.0 | "PVLP004" | true | false | true |
| "LC9" | 720575940647674676 | 29 | 84 | 6 | 0.065217 | "LMa1" | true | false | true |
| "LC9" | 720575940648685444 | 28 | 101 | 8 | 0.086957 | "LMa1" | true | false | true |
Discussion
A large share of each type's output synapses lands on fragments, and the weak bulk is almost all fragments. Proofread neurons are a small part of each type's partners but receive a large share of its output synapses (Who the partners are). Counting fragments as partners adds few strong ones (Strengths from each type to its proofread partners).
Strong partners are few and receive most of the synapses that reach neurons. Under every choice of partners the strong set is a small fraction of the partners and a much larger fraction of the output synapses (How much the strong set carries), so the expectation holds.
Most strong partners of LC11 and LC9 are LC cells, mostly of other LC types (Lateral connections). Leaving the LC cells out shrinks the strong sets, but they still carry most of the synapses that go to proofread partners that are not LC cells (How much the strong set carries).
The cutoff is a standard here.
Downstream notebooks import strong_set,
which takes the proofread partners with
\(s \ge\) STRONG_SYN = 10
and removes the LC cells from them.
The cutoff rests on the release paper's "large connection" of more
than nine synapses and on Dr. Chiappe's suggestion;
lc_output_strength_definitions
checks it against the distribution of strengths.
Limitations
Fragments are unattached pieces of neurons, so the strength from a type to a proofread partner is a lower bound: attaching its loose twigs would add synapses and could raise its strength. The weights are the synapse counts of the Codex release, which come from an automated detector whose dominant error, the release paper says, is false negatives, so they are lower bounds too.
Open questions
- Are the strong connections onto other LC types reciprocal? Test: load the connections that start at the LC cells that receive them and compare the weight of each strong pair in the two directions. Pairs with no strong return are one-way connections; reciprocal pairs are mutual.
- Do the strong partners of a type sit near each other, as the partners of one glomerulus would? Test: locate each strong partner by the neuropil of its connections (Codex connection tables carry one) or by the positions of its synapses, and compare the spread of a type's strong partners with the spread of its weak ones.
Terms
- connection: all the synapses from cell \(i\) to cell \(j\).
One synapse is enough here, as in the name of Codex's
connections_princeton_no_thresholdtable; the release paper calls two neurons connected only at five or more. - lateral connection: a connection onto an LC cell. That cell is a lateral partner.
- partner: a postsynaptic segment of a connection from some cell of a type, either a proofread neuron or an unproofread fragment. LC cells count.
- proofread neuron: a segment that people have proofread and
joined into a neuron (
proofread_ids). Nearly all have a type in the census. - strength \(s(T \to j)\): the weight of the heaviest single connection from a cell of the type \(T\) onto the partner \(j\). A weight belongs to one connection; a strength belongs to a type and one of its partners.
- twig: a thin terminal branch of a neuron.
- unproofread fragment: an automated segment that is not a proofread neuron. It may be a piece of a neuron that is already a partner, or of another one, so its weight counts only the synapses on that piece.
- weight \(w(i \to j)\): the number of synapses in the connection from \(i\) to \(j\).