LC pathway topology
Introduction
Question
Do LC10a, LC9, LC11, and LC16 form convergent, parallel, or divergent pathways?
Background
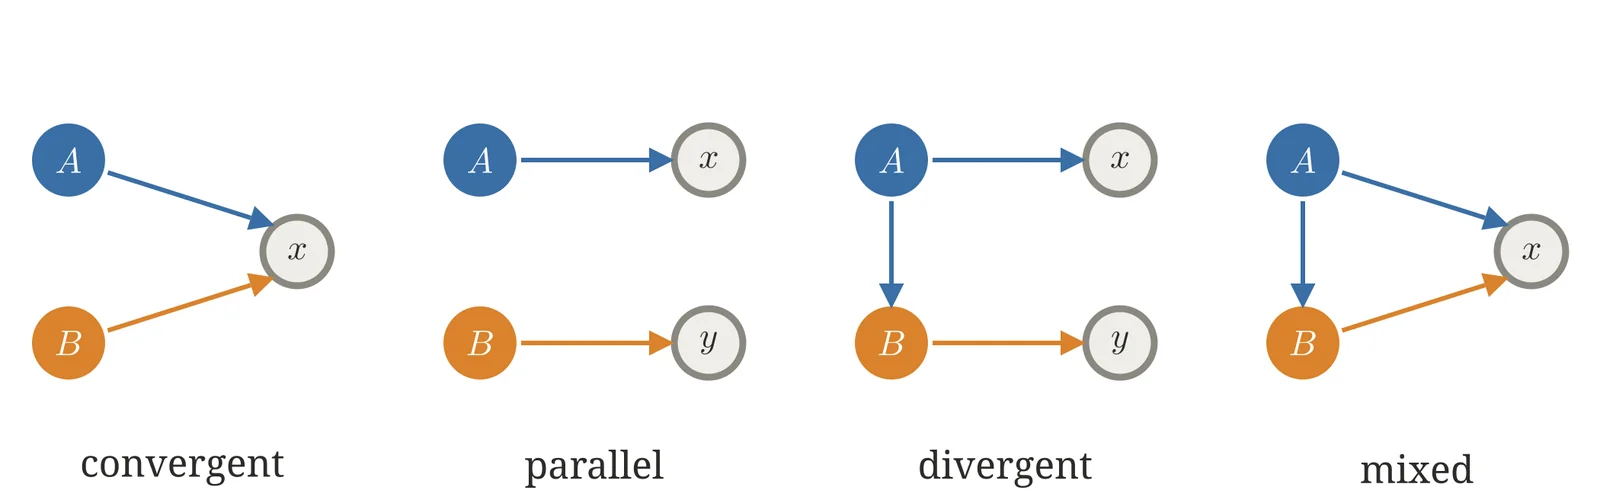
Dr. Chiappe proposed three models for how the outputs of the types relate to each other. "The same cells" means the same cells, not only the same types.
- Convergent: the types reach the same postsynaptic cells, directly or through one intermediate cell.
- Parallel: the types share no postsynaptic cells and do not connect to each other.
- Divergent: the types connect to each other, but their postsynaptic cells stay apart.
A connection from a cell of one of the types onto a cell of another is a lateral connection. Types that both converge and connect laterally fit none of the three, and are called mixed here. The schematic shows the four cases for two types, \(A\) and \(B\), and two postsynaptic cells.
Convergence is measured by the Jaccard index of the strong partners
of two types,
the cells that each type connects to strongly
(lc_output_strength defines a
strong partner).
It uses the right hemisphere only,
the better-proofread side,
as Dr. Chiappe suggested.
Expectations
- If two types converge, they share strong partner cells:
the Jaccard index of their strong partners is at least
CONVERGENCE_JACCARD= 0.05, for the cells they send to, the cells that send to them, or the cells that their partners send to in turn (two hops). If they do not, their partner sets overlap by chance at most, and the index stays below it. - If two types connect laterally, some cell of one connects to a cell of the other, and the synapses between the types are above zero. If none do, the lateral synapses between different types are zero.
Load data
The analysis reads census, which gives each cell's type,
sides, which says which hemisphere a cell is in,
and proofread_ids, which lists the proofread neurons.
| root_id | primary_type |
|---|---|
| i64 | str |
| 720575940599457990 | "T4b" |
| 720575940599763910 | "T5b" |
| 720575940600623020 | "Dm3q" |
| 720575940602564320 | "KCg-m" |
| 720575940602720940 | "JO-CA" |
| … | … |
| 720575940661275009 | "KCab-p" |
| 720575940661281409 | "L4" |
| 720575940661285249 | "LPC2" |
| 720575940661304449 | "Lawf1" |
| 720575940661333889 | "CB2303" |
| root_id | side |
|---|---|
| i64 | str |
| 720575940596125868 | "right" |
| 720575940597856265 | "right" |
| 720575940597944841 | "right" |
| 720575940598267657 | "right" |
| 720575940599333574 | "right" |
| … | … |
| 720575940661323905 | "left" |
| 720575940661325697 | "left" |
| 720575940661327745 | "right" |
| 720575940661336193 | "left" |
| 720575940661339777 | "right" |
| root_id |
|---|
| i64 |
| 720575940599457990 |
| 720575940599763910 |
| 720575940600623020 |
| 720575940602309600 |
| 720575940602564320 |
| … |
| 720575940661275009 |
| 720575940661281409 |
| 720575940661285249 |
| 720575940661304449 |
| 720575940661333889 |
The types are restricted to the right hemisphere.
cells = cells_of_types(census, sides, TYPES_OF_INTEREST)
pl.DataFrame(
    {
        "type": list(TYPES_OF_INTEREST),
        "right-hemisphere cells": [
            len(cells[_t]) for _t in TYPES_OF_INTEREST
        ],
    }
)
| type | right-hemisphere cells |
|---|---|
| str | i64 |
| "LC10a" | 121 |
| "LC9" | 92 |
| "LC11" | 61 |
| "LC16" | 74 |
connections has one row per connection that starts at one of
those cells, with its weight and the type of its presynaptic cell
(pre_type).
These are the outputs of the types.
input_connections has the connections that end at those cells,
with the two ends swapped (reversed_connections),
so that pre_pt_root_id is the LC cell, pre_type its type,
and post_pt_root_id the cell that sends to it.
A strength then reads the same way for inputs as for outputs.
_scored = [_id for _ids in cells.values() for _id in _ids]
connections = with_pre_type(load_connections_of(_scored), cells)
connections
| pre_pt_root_id | post_pt_root_id | weight | pre_type |
|---|---|---|---|
| i64 | i64 | i64 | str |
| 720575940603578848 | 720575940381391499 | 1 | "LC11" |
| 720575940603578848 | 720575940381415307 | 1 | "LC11" |
| 720575940603578848 | 720575940381421195 | 1 | "LC11" |
| 720575940603578848 | 720575940381425291 | 1 | "LC11" |
| 720575940603578848 | 720575940381433227 | 1 | "LC11" |
| … | … | … | … |
| 720575940659229057 | 720575940649865718 | 1 | "LC11" |
| 720575940659229057 | 720575940650149753 | 2 | "LC11" |
| 720575940659229057 | 720575940651404278 | 2 | "LC11" |
| 720575940659229057 | 720575940653346038 | 2 | "LC11" |
| 720575940659229057 | 720575940661134465 | 1 | "LC11" |
_scored = [_id for _ids in cells.values() for _id in _ids]
input_connections = with_pre_type(
    reversed_connections(load_connections_of(_scored, end="post")), cells
)
input_connections
| post_pt_root_id | pre_pt_root_id | weight | pre_type |
|---|---|---|---|
| i64 | i64 | i64 | str |
| 720575940379617287 | 720575940605242242 | 1 | "LC16" |
| 720575940379635975 | 720575940613168554 | 1 | "LC16" |
| 720575940379671303 | 720575940614712115 | 1 | "LC16" |
| 720575940379697671 | 720575940624123536 | 1 | "LC16" |
| 720575940379736406 | 720575940634144875 | 1 | "LC11" |
| … | … | … | … |
| 720575940661316993 | 720575940622014758 | 1 | "LC16" |
| 720575940661316993 | 720575940627874832 | 1 | "LC16" |
| 720575940661318017 | 720575940617836117 | 4 | "LC9" |
| 720575940661318017 | 720575940636578014 | 1 | "LC11" |
| 720575940661320065 | 720575940627676798 | 1 | "LC10a" |
Lateral connections
The lateral synapses from type \(A\) to type \(B\) are the synapses of the connections from cells of \(A\) onto cells of \(B\),
where \(w(i \to j)\) is the weight of the connection
(the number of its synapses).
lateral_synapses returns \(L\) for every pair of the given types,
with 0 for a pair with no connection.
It needs the type of both ends,
so the connections get post_type from with_post_type first.
On three connections among two types:
def lateral_synapses(
    connections: pl.DataFrame, types: Sequence[str]
) -> pl.DataFrame:
    """The synapses from each type to each type of types.

    connections is DataFrame[pre_type, post_type, weight].
    DataFrame[pre_type, post_type, synapses], one row for every ordered
    pair of types, the diagonal included.
    """
    every_pair = pl.DataFrame(
        {
            "pre_type": [a for a in types for _ in types],
            "post_type": [b for _ in types for b in types],
        }
    )
    sums = (
        connections.drop_nulls(["pre_type", "post_type"])
        .group_by("pre_type", "post_type")
        .agg(synapses=pl.col("weight").sum())
    )
    return (
        every_pair.join(sums, on=["pre_type", "post_type"], how="left")
        .with_columns(pl.col("synapses").fill_null(0))
        .sort(
            pl.col("pre_type").replace_strict(
                {t: n for n, t in enumerate(types)}
            ),
            pl.col("post_type").replace_strict(
                {t: n for n, t in enumerate(types)}
            ),
        )
    )
lateral_synapses(
    pl.DataFrame(
        {
            "pre_type": ["A", "A", "B"],
            "post_type": ["B", "B", "B"],
            "weight": [4, 1, 2],
        }
    ),
    ["A", "B"],
)
| pre_type | post_type | synapses |
|---|---|---|
| str | str | i64 |
| "A" | "A" | 0 |
| "A" | "B" | 5 |
| "B" | "A" | 0 |
| "B" | "B" | 2 |
Rows send and columns receive. The diagonal is contact within a type; any synapse off the diagonal is a lateral connection between types.
lateral = lateral_synapses(
    with_post_type(connections, cells), TYPES_OF_INTEREST
)
_heat = (
    alt.Chart(lateral)
    .encode(
        x=alt.X(
            "post_type:N",
            sort=list(TYPES_OF_INTEREST),
            title="receives",
            axis=alt.Axis(labelAngle=0),
        ),
        y=alt.Y("pre_type:N", sort=list(TYPES_OF_INTEREST), title="sends"),
    )
    .properties(width=260, height=200)
)
_cells = _heat.mark_rect().encode(
    color=alt.Color(
        "synapses:Q",
        scale=alt.Scale(scheme="greys", type="symlog"),
        legend=None,
    ),
    tooltip=[
        "pre_type:N",
        "post_type:N",
        alt.Tooltip("synapses:Q", format=","),
    ],
)
_text = _heat.mark_text().encode(
    text=alt.Text("synapses:Q", format=","),
    color=alt.condition(
        alt.datum.synapses > lateral["synapses"].to_numpy().max() / 4,
        alt.value("white"),
        alt.value("black"),
    ),
)
_cells + _text
The strongest single connections between different types:
with_post_type(connections, cells).filter(
    pl.col("post_type").is_not_null()
    & (pl.col("pre_type") != pl.col("post_type"))
).sort("weight", descending=True).head(10).select(
    "pre_type",
    "pre_pt_root_id",
    "post_type",
    "post_pt_root_id",
    "weight",
)
| pre_type | pre_pt_root_id | post_type | post_pt_root_id | weight |
|---|---|---|---|---|
| str | i64 | str | i64 | i64 |
| "LC9" | 720575940626613609 | "LC10a" | 720575940625893834 | 41 |
| "LC9" | 720575940635224943 | "LC10a" | 720575940631264140 | 35 |
| "LC9" | 720575940619719668 | "LC10a" | 720575940648939897 | 33 |
| "LC9" | 720575940632603873 | "LC10a" | 720575940623448078 | 32 |
| "LC9" | 720575940616204059 | "LC10a" | 720575940622187329 | 31 |
| "LC9" | 720575940635703262 | "LC10a" | 720575940622917876 | 28 |
| "LC9" | 720575940621415382 | "LC10a" | 720575940613561868 | 25 |
| "LC9" | 720575940607313756 | "LC10a" | 720575940636302143 | 23 |
| "LC9" | 720575940614303890 | "LC10a" | 720575940615833574 | 23 |
| "LC9" | 720575940618541995 | "LC10a" | 720575940622366448 | 23 |
Partner overlap
The partners of a type are the cells on the other side of its
connections:
the cells it sends to are its output partners,
and the cells that send to it are its input partners.
The strong partners are the proofread partners with a strength of
at least STRONG_SYN, without the LC cells among them
(strong_set of lc_output_strength, with the table of partners
from labeled_partners below),
so a lateral connection does not count as a shared partner.
The strength from a type to an output partner is the weight of the
heaviest connection from one of its cells onto it,
and the strength from an input partner to a type is the weight of
the heaviest connection from it onto one of the type's cells.
labeled_partners gives the partners of each type
from connections that start at its cells
(connections for the outputs, input_connections for the inputs),
labeled by label_partners of lc_output_strength.
On two cells of one type that make one strong and one weak
connection:
def labeled_partners(
    connections: pl.DataFrame,
    cells: dict[str, list[int]],
    census: pl.DataFrame,
    proofread_ids: pl.DataFrame,
) -> pl.DataFrame:
    """The partners of each type, from the connections that start at
    its cells.

    connections carry pre_type, as with_pre_type adds it from cells,
    which maps a type name to the ids of its cells.
    DataFrame[type, partner, s, synapses, cells, cell_fraction,
    partner_type, proofread, lateral], as label_partners returns it.
    """
    return label_partners(
        strengths_to_partners_with_cell_fraction(connections, cells),
        census,
        proofread_ids,
    )
_cells = {"T": ["t1", "t2"]}
strong_set(
    labeled_partners(
        with_pre_type(
            pl.DataFrame(
                {
                    "pre_pt_root_id": ["t1", "t2", "t1"],
                    "post_pt_root_id": ["j", "j", "k"],
                    "weight": [12, 3, 4],
                }
            ),
            _cells,
        ),
        _cells,
        pl.DataFrame({"root_id": ["j", "k"], "primary_type": ["X", "Y"]}),
        pl.DataFrame({"root_id": ["j", "k"]}),
    ),
    cutoff=10,
)
| type | partner | s | synapses | cells | cell_fraction | partner_type | proofread | lateral |
|---|---|---|---|---|---|---|---|---|
| str | str | i64 | i64 | u32 | f64 | str | bool | bool |
| "T" | "j" | 12 | 15 | 2 | 1.0 | "X" | true | false |
partners_out = labeled_partners(connections, cells, census, proofread_ids)
partners_in = labeled_partners(
    input_connections, cells, census, proofread_ids
)
strong_out = strong_set(partners_out)
strong_in = strong_set(partners_in)
pl.DataFrame(
    {
        "type": list(TYPES_OF_INTEREST),
        "strong output partners": [
            strong_out.filter(pl.col("type") == _t).height
            for _t in TYPES_OF_INTEREST
        ],
        "strong input partners": [
            strong_in.filter(pl.col("type") == _t).height
            for _t in TYPES_OF_INTEREST
        ],
    }
)
| type | strong output partners | strong input partners |
|---|---|---|
| str | i64 | i64 |
| "LC10a" | 85 | 110 |
| "LC9" | 89 | 120 |
| "LC11" | 132 | 1695 |
| "LC16" | 35 | 385 |
Overlap between two types is the Jaccard index of their sets of strong partners, \(J(A, B) = |A \cap B| / |A \cup B|\), at two levels:
- cell: the same partner cells. This is Dr. Chiappe's test.
- type: the same kinds of partner cells. It is context only, since two types can each drive a private copy of the same partner type.
sets_by_type collects a column of the strong partners into one
set for each type,
and pairwise_jaccard gives the index for every pair of sets.
On two types that share two of four partners:
def sets_by_type(
    strong: pl.DataFrame, column: str, types: Sequence[str]
) -> dict[str, set]:
    """The values of column among the rows of strong of each type, as
    {type: set}; a type with no row has an empty set.

    strong is DataFrame[type, ...].
    """
    return {
        t: set(strong.filter(pl.col("type") == t)[column].to_list())
        for t in types
    }
def pairwise_jaccard(sets: dict[str, set]) -> pl.DataFrame:
    """The Jaccard index of every pair of the sets.

    DataFrame[a, b, jaccard, shared, union]: shared and union are the
    sizes of the intersection and the union of the two sets.
    """
    return pl.DataFrame(
        [
            {
                "a": a,
                "b": b,
                "jaccard": jaccard(sets[a], sets[b]),
                "shared": len(sets[a] & sets[b]),
                "union": len(sets[a] | sets[b]),
            }
            for a, b in combinations(sets, 2)
        ],
        schema={
            "a": pl.String,
            "b": pl.String,
            "jaccard": pl.Float64,
            "shared": pl.Int64,
            "union": pl.Int64,
        },
    )
_strong = pl.DataFrame(
    {
        "type": ["P", "P", "P", "Q", "Q", "Q"],
        "partner": [1, 2, 3, 2, 3, 4],
    }
)
pairwise_jaccard(sets_by_type(_strong, "partner", ["P", "Q"]))
| a | b | jaccard | shared | union |
|---|---|---|---|---|
| str | str | f64 | i64 | i64 |
| "P" | "Q" | 0.5 | 2 | 4 |
jaccards holds the index of every pair of types:
at the cell and the type level,
for the output partners and the input partners.
A partner that is a proofread neuron the census does not name has
no type to compare, so it is left out of the type level.
_named = pl.col("partner_type") != "untyped neuron"
_sets = {
    ("cell", "output"): sets_by_type(
        strong_out, "partner", TYPES_OF_INTEREST
    ),
    ("cell", "input"): sets_by_type(
        strong_in, "partner", TYPES_OF_INTEREST
    ),
    ("type", "output"): sets_by_type(
        strong_out.filter(_named), "partner_type", TYPES_OF_INTEREST
    ),
    ("type", "input"): sets_by_type(
        strong_in.filter(_named), "partner_type", TYPES_OF_INTEREST
    ),
}
jaccards = pl.concat(
    [
        pairwise_jaccard(_by_type).with_columns(
            level=pl.lit(_level), side=pl.lit(_side)
        )
        for (_level, _side), _by_type in _sets.items()
    ]
)
jaccards.with_columns(measure=pl.format("{}, {}", "level", "side")).pivot(
    on="measure", index=["a", "b"], values="jaccard"
)
| a | b | cell, output | cell, input | type, output | type, input |
|---|---|---|---|---|---|
| str | str | f64 | f64 | f64 | f64 |
| "LC10a" | "LC9" | 0.067485 | 0.045455 | 0.025 | 0.114286 |
| "LC10a" | "LC11" | 0.0 | 0.00838 | 0.010526 | 0.149254 |
| "LC10a" | "LC16" | 0.0 | 0.016427 | 0.0 | 0.18 |
| "LC9" | "LC11" | 0.018433 | 0.003872 | 0.042553 | 0.0875 |
| "LC9" | "LC16" | 0.00813 | 0.01 | 0.053571 | 0.112903 |
| "LC11" | "LC16" | 0.006024 | 0.003861 | 0.013889 | 0.133333 |
The shared output cells behind the highest cell-level overlap of the output partners:
_best = (
    jaccards.filter(
        (pl.col("level") == "cell") & (pl.col("side") == "output")
    )
    .sort("jaccard", descending=True)
    .row(0, named=True)
)
_by_type = sets_by_type(strong_out, "partner", TYPES_OF_INTEREST)
_shared = _by_type[_best["a"]] & _by_type[_best["b"]]
mo.vstack(
    [
        mo.md(
            f"Output partners shared by {_best['a']} and {_best['b']} "
            f"({len(_shared)} cells):"
        ),
        strong_out.filter(pl.col("partner").is_in(list(_shared)))
        .select("partner", "partner_type")
        .unique()
        .sort("partner_type", "partner"),
    ]
)
| partner | partner_type |
|---|---|
| i64 | str |
| 720575940617019442 | "LMa1" |
| 720575940618467513 | "LMa1" |
| 720575940619714974 | "LMa1" |
| 720575940623016709 | "LMa1" |
| 720575940627249850 | "LMa1" |
| … | … |
| 720575940629900816 | "LMa1" |
| 720575940632330538 | "LMa1" |
| 720575940633007953 | "LMa1" |
| 720575940612752611 | "LT82" |
| 720575940634356587 | "LT82" |
How the cutoff changes the overlap
STRONG_SYN is a standard, not a measurement,
and the overlap is a ratio of two sets that the cutoff resizes.
overlap_by_cutoff recomputes the cell-level overlap of the
strong partners at each cutoff in CUTOFFS
and keeps the pair with the highest index.
On a partner for each of two types, strong at the lower cutoff
only:
def overlap_by_cutoff(
    partners: pl.DataFrame, types: Sequence[str], cutoffs: Sequence[int]
) -> pl.DataFrame:
    """The pair of types with the highest cell-level overlap of strong
    partners at each cutoff.

    partners is DataFrame[type, partner, s, proofread, lateral, ...],
    as labeled_partners returns it.
    DataFrame[cutoff, a, b, jaccard]; with fewer than two types it has
    no rows.
    """
    return pl.concat(
        [
            pairwise_jaccard(
                sets_by_type(
                    strong_set(partners, cutoff=cutoff), "partner", types
                )
            )
            .sort("jaccard", descending=True)
            .head(1)
            .with_columns(cutoff=pl.lit(cutoff))
            for cutoff in cutoffs
        ]
    ).select("cutoff", "a", "b", "jaccard")
overlap_by_cutoff(
    pl.DataFrame(
        {
            "type": ["P", "P", "Q", "Q"],
            "partner": [1, 2, 1, 3],
            "s": [20, 5, 20, 5],
            "proofread": [True] * 4,
            "lateral": [False] * 4,
        }
    ),
    ["P", "Q"],
    [5, 20],
)
| cutoff | a | b | jaccard |
|---|---|---|---|
| i32 | str | str | f64 |
| 5 | "P" | "Q" | 0.333333 |
| 20 | "P" | "Q" | 1.0 |
cutoff_overlap = pl.concat(
    [
        overlap_by_cutoff(_p, TYPES_OF_INTEREST, CUTOFFS).with_columns(
            side=pl.lit(_side)
        )
        for _side, _p in (("output", partners_out), ("input", partners_in))
    ]
)
_lines = (
    alt.Chart(cutoff_overlap)
    .mark_line(point=True)
    .encode(
        x=alt.X(
            "cutoff:Q",
            scale=alt.Scale(type="log"),
            axis=alt.Axis(values=list(CUTOFFS)),
            title="cutoff (synapses)",
        ),
        y=alt.Y("jaccard:Q", title="largest Jaccard index of a pair"),
        color=alt.Color(
            "side:N",
            scale=alt.Scale(
                domain=["output", "input"],
                range=[DIRECTION_COLORS["out"], DIRECTION_COLORS["in"]],
            ),
        ),
        tooltip=[
            "side:N",
            "cutoff:Q",
            "a:N",
            "b:N",
            alt.Tooltip("jaccard:Q", format=".3f"),
        ],
    )
)
_threshold = (
    alt.Chart(pl.DataFrame({"y": [CONVERGENCE_JACCARD]}))
    .mark_rule(strokeDash=[4, 4], color=CONTEXT_COLOR)
    .encode(y="y:Q")
)
(_lines + _threshold).properties(width=360, height=200)
Communities
A community is a group of types that connect more to each other
than to the rest.
The graph has a node for each LC type and for each type of its
strong partners,
and an edge between an LC type and a partner type with the
synapses the LC type sends to the strong partners of that type
and receives from them, added up.
One community per LC type would suggest private channels;
LC types in one community would suggest convergence.
type_mass gives the synapses behind the edges.
On the strong partners of the earlier demo:
def type_mass(strong: pl.DataFrame) -> pl.DataFrame:
    """The synapses between each type and the strong partners of each
    partner type, heaviest first within a type.

    strong is DataFrame[type, partner_type, synapses, ...], as
    labeled_partners returns it; a partner that is a proofread neuron
    with no type in the census is left out.
    DataFrame[type, partner_type, synapses].
    """
    return (
        strong.filter(pl.col("partner_type") != "untyped neuron")
        .group_by("type", "partner_type")
        .agg(pl.col("synapses").sum())
        .sort(
            "type", "synapses", "partner_type", descending=[False, True, False]
        )
    )
type_mass(
    pl.DataFrame(
        {
            "type": ["T", "T", "T"],
            "partner_type": ["X", "X", "Y"],
            "synapses": [12, 8, 30],
        }
    )
)
| type | partner_type | synapses |
|---|---|---|
| str | str | i64 |
| "T" | "Y" | 30 |
| "T" | "X" | 20 |
type_communities finds the communities of that graph by greedy
modularity maximization.
It is one method among several (Louvain, label propagation);
it is deterministic, which keeps the table stable between runs.
On two LC types that share a partner type and one that does not:
def type_communities(mass: pl.DataFrame) -> list[set[str]]:
    """The communities of the graph with an edge between type and
    partner_type for each row of mass, weighted by its synapses.

    mass is DataFrame[type, partner_type, synapses]; rows for the same
    pair of types add up, whichever of the two is the type.
    """
    graph = nx.Graph()
    for row in mass.iter_rows(named=True):
        pair = (row["type"], row["partner_type"])
        previous = (
            graph[pair[0]][pair[1]]["weight"] if graph.has_edge(*pair) else 0
        )
        graph.add_edge(*pair, weight=previous + row["synapses"])
    communities = nx.algorithms.community.greedy_modularity_communities(
        graph, weight="weight"
    )
    return [set(community) for community in communities]
sorted(
    sorted(_c)
    for _c in type_communities(
        pl.DataFrame(
            {
                "type": ["P", "P", "Q", "R"],
                "partner_type": ["X", "Y", "X", "Z"],
                "synapses": [10, 3, 10, 9],
            }
        )
    )
)
- 0: list · 4 items
- 0: 'P'
- 1: 'Q'
- 2: 'X'
- 3: 'Y'
- 1: list · 2 items
- 0: 'R'
- 1: 'Z'
mass = (
    pl.concat([type_mass(strong_out), type_mass(strong_in)])
    .group_by("type", "partner_type")
    .agg(pl.col("synapses").sum())
)
_rows = []
for _community in type_communities(mass):
    _partners = (
        mass.filter(pl.col("partner_type").is_in(list(_community)))
        .group_by("partner_type")
        .agg(pl.col("synapses").sum())
        .sort("synapses", descending=True)
        .head(8)["partner_type"]
        .to_list()
    )
    _rows.append(
        {
            "types": ", ".join(
                sorted(_community & set(TYPES_OF_INTEREST))
            ),
            "members": len(_community),
            "heaviest partner types": ", ".join(_partners),
        }
    )
pl.DataFrame(_rows).sort("members", descending=True)
| types | members | heaviest partner types |
|---|---|---|
| str | i64 | str |
| "LC11" | 81 | "T3, T2, CB0732, cL21, Li15, AV… |
| "LC9" | 64 | "PVLP004, LMa1, LT56, PVLP070, … |
| "LC10a" | 55 | "TuTuAa, AOTU041, LT52, AOTU042… |
| "LC16" | 28 | "PVLP007, Li33, PVLP008, Tm20, … |
Two hops
Indirect convergence is two types reaching the same cell \(Y\)
through their own strong output partners \(X\),
\(t \to X \to Y\).
The \(X\) cells of a type are its strong output partners,
and \(Y\) is a proofread neuron that is not an LC cell and that some
\(X\) connects to with at least STRONG_SYN synapses.
The sets of \(Y\) are large,
so they are compared by the Jaccard index and not by raw counts.
second_hop_cells gives the \(Y\) of one set of \(X\).
On two sources that reach three cells,
one of them a source:
def second_hop_cells(
    connections: pl.DataFrame,
    sources: set[int],
    candidates: set[int],
    *,
    cutoff: int = STRONG_SYN,
) -> set[int]:
    """The cells of candidates, other than the sources, that a source
    connects to with a weight of at least cutoff.

    connections is DataFrame[pre_pt_root_id, post_pt_root_id, weight].
    """
    reached = connections.filter(
        pl.col("pre_pt_root_id").is_in(list(sources))
        & (pl.col("weight") >= cutoff)
    )["post_pt_root_id"]
    return (set(reached.to_list()) & candidates) - sources
second_hop_cells(
    pl.DataFrame(
        {
            "pre_pt_root_id": [1, 1, 2, 2, 3],
            "post_pt_root_id": [2, 5, 6, 7, 8],
            "weight": [12, 11, 15, 4, 20],
        }
    ),
    sources={1, 2},
    candidates={2, 5, 6, 7, 8},
    cutoff=10,
)
{5, 6}
_sources = {
    _t: set(sets_by_type(strong_out, "partner", TYPES_OF_INTEREST)[_t])
    for _t in TYPES_OF_INTEREST
}
_lc = set(
    census.filter(pl.col("primary_type").str.contains(r"^LC\d"))[
        "root_id"
    ].to_list()
)
_neurons = set(proofread_ids["root_id"].to_list()) - _lc
_hop_connections = load_connections_of(
    sorted(set().union(*_sources.values())), min_weight=STRONG_SYN
)
hop = {
    _t: second_hop_cells(_hop_connections, _sources[_t], _neurons)
    for _t in TYPES_OF_INTEREST
}
pl.DataFrame(
    {
        "type": list(TYPES_OF_INTEREST),
        "first-hop cells X": [
            len(_sources[_t]) for _t in TYPES_OF_INTEREST
        ],
        "second-hop cells Y": [len(hop[_t]) for _t in TYPES_OF_INTEREST],
    }
)
| type | first-hop cells X | second-hop cells Y |
|---|---|---|
| str | i64 | i64 |
| "LC10a" | 85 | 1042 |
| "LC9" | 89 | 2551 |
| "LC11" | 132 | 3089 |
| "LC16" | 35 | 859 |
jaccards_with_hop = pl.concat(
    [
        jaccards,
        pairwise_jaccard(hop).with_columns(
            level=pl.lit("cell"), side=pl.lit("two hops")
        ),
    ]
)
jaccards_with_hop.filter(pl.col("side") == "two hops")
| a | b | jaccard | shared | union | level | side |
|---|---|---|---|---|---|---|
| str | str | f64 | i64 | i64 | str | str |
| "LC10a" | "LC9" | 0.171503 | 526 | 3067 | "cell" | "two hops" |
| "LC10a" | "LC11" | 0.070207 | 271 | 3860 | "cell" | "two hops" |
| "LC10a" | "LC16" | 0.034839 | 64 | 1837 | "cell" | "two hops" |
| "LC9" | "LC11" | 0.189873 | 900 | 4740 | "cell" | "two hops" |
| "LC9" | "LC16" | 0.067627 | 216 | 3194 | "cell" | "two hops" |
| "LC11" | "LC16" | 0.093326 | 337 | 3611 | "cell" | "two hops" |
Decision rule
A pair of types is convergent when its cell-level Jaccard index is
at least CONVERGENCE_JACCARD
for outputs, inputs, or two hops;
the set of types is convergent when any pair is.
It is lateral when any synapse runs between different types.
| convergent | lateral | label |
|---|---|---|
| yes | yes | convergent and lateral (mixed) |
| yes | no | convergent |
| no | yes | divergent |
| no | no | parallel |
largest_overlap finds the pair with the highest index of a
kind,
and score_model applies the rule and returns a Verdict.
class Overlap(NamedTuple):
    """The pair of types with the highest Jaccard index of a kind."""

    a: str
    b: str
    jaccard: float
def largest_overlap(
    jaccards: pl.DataFrame, *, level: str, side: str
) -> Overlap:
    """The pair with the highest index among the rows of jaccards of
    this level ("cell" or "type") and side ("output", "input", or
    "two hops").

    jaccards is DataFrame[a, b, jaccard, level, side, ...].
    Raises ValueError when no row has that level and side.
    """
    rows = jaccards.filter(
        (pl.col("level") == level) & (pl.col("side") == side)
    )
    if rows.is_empty():
        msg = f"no row has level {level!r} and side {side!r}"
        raise ValueError(msg)
    best = rows.sort("jaccard", descending=True).row(0, named=True)
    return Overlap(best["a"], best["b"], best["jaccard"])
largest_overlap(
    pl.DataFrame(
        {
            "a": ["P", "P"],
            "b": ["Q", "R"],
            "jaccard": [0.1, 0.3],
            "level": ["cell", "cell"],
            "side": ["output", "output"],
        }
    ),
    level="cell",
    side="output",
)
Overlap(a='P', b='R', jaccard=0.3)
class Verdict(NamedTuple):
    """The label of a set of types and the two findings behind it.

    label is one of "convergent and lateral (mixed)", "convergent",
    "divergent", and "parallel".
    """

    label: str
    lateral: bool
    convergent: bool
def score_model(
    lateral_synapses_between_types: int,
    jaccards: pl.DataFrame,
    *,
    threshold: float = CONVERGENCE_JACCARD,
) -> Verdict:
    """Dr. Chiappe's label for a set of types.

    lateral_synapses_between_types is the sum of L(A, B) over the
    pairs of different types.
    jaccards is DataFrame[jaccard, level, side, ...]; the types
    converge when a cell-level index of the output, input, or
    two-hops partners is at least threshold.
    """
    cell_level = jaccards.filter(
        (pl.col("level") == "cell")
        & pl.col("side").is_in(["output", "input", "two hops"])
    )
    convergent = bool((cell_level["jaccard"] >= threshold).any())
    lateral = lateral_synapses_between_types > 0
    if convergent and lateral:
        label = "convergent and lateral (mixed)"
    elif convergent:
        label = "convergent"
    elif lateral:
        label = "divergent"
    else:
        label = "parallel"
    return Verdict(label=label, lateral=lateral, convergent=convergent)
Verdict(label='divergent', lateral=True, convergent=False)
_off_diagonal = int(
    lateral.filter(pl.col("pre_type") != pl.col("post_type"))[
        "synapses"
    ].sum()
)
verdict = score_model(_off_diagonal, jaccards_with_hop)
verdict
Verdict(label='convergent and lateral (mixed)', lateral=True, convergent=True)
Verdict: convergent and lateral (mixed)
Discussion
Expectation 1: some pairs of types share strong partner cells. The largest cell-level Jaccard index is 0.067 for outputs (LC10a and LC9), 0.045 for inputs (LC10a and LC9), and 0.190 at two hops (LC9 and LC11), against CONVERGENCE_JACCARD = 0.05. Pairs that reach it, of 6: 1 for outputs, 0 for inputs, and 5 at two hops. The largest type-level output index is 0.05 (LC9 and LC16) (Partner overlap).
Expectation 2: the types connect to each other. The types exchange 7,120 synapses off the diagonal, the largest flows being LC9 to LC10a (2,853), LC11 to LC9 (1,250), and LC11 to LC16 (1,127) (Lateral connections).
The verdict depends on the cutoff. The largest output index is at or above CONVERGENCE_JACCARD at the cutoffs 5 and 10 and below it at 20 and 40; the largest input index is at or above it at 5 and below it at 10, 20, and 40 (How the cutoff changes the overlap). The standard is STRONG_SYN = 10.
Skeptic's case.
A shared strong partner is not shared function:
a partner cell that receives from every LC type counts toward the
overlap of every pair, and the index has no chance level of its
own, since two large sets overlap more by chance than two small
ones.
In the other direction, a whole-type index is small whenever
outputs are retinotopic,
even if two types converge within every patch of the visual field,
because each patch's partners are a small share of the union over
all patches;
lc_output_clusters shows that the cells of LC10a and LC9 fall in
parts of the column grid, so this is a live concern.
Conclusion.
The verdict is convergent and lateral (mixed) at the standard cutoff.
The overlap falls below CONVERGENCE_JACCARD at some cutoffs, so the standard cutoff is a choice that decides the verdict.
It stands only until the overlap is measured between
retinotopically matched cells (Open questions).
Limitations
The weights are the synapse counts of the Codex release, and the
strong partners are the proofread ones,
so the strength of a partner is a lower bound
(lc_output_strength gives the reason).
The analysis uses the right hemisphere only,
so connections between the two sides are not counted.
The two-hop sets are large (LC10a 1,042, LC9 2,551, LC11 3,089, and LC16 859 cells),
so their index is more sensitive to cells that many first-hop cells
connect to.
CONVERGENCE_JACCARD is a choice, not a measured chance level.
Open questions
- Within matched column neighborhoods, LC10a and LC9 share more
strong output partners than the whole-type index suggests.
Test: bin both types by address (
lc_output_clusters), compute the index of strong partners per matched bin, and compare it with mismatched bins. Refuted if the two give the same index. - The lateral synapses from LC9 onto LC10a connect cells with nearby addresses. Test: the address distance of connected LC9 and LC10a pairs against random pairs of the two types. Refuted if the distances match.
- The shared strong partners receive from many LC types, not only the pair that shares them. Test: the number of LC types that connect strongly to each shared cell, against the same number for the strong partners that are not shared. Refuted if the two numbers match.
Terms
- community: a group of types that connect more to each other than to the rest of the graph of types and their strong partner types.
- connection: all the synapses from cell \(i\) to cell \(j\).
- convergent, parallel, divergent: Dr. Chiappe's three models (see Background).
- input partner: a cell that sends a connection onto some cell of a type.
- Jaccard index \(J(A, B) = |A \cap B| / |A \cup B|\): the share of the union of two sets that they have in common.
- lateral connection: a connection from a cell of one of the types onto a cell of another of them (or of the same one, on the diagonal of \(L\)).
- output partner: a cell that receives a connection from some cell of a type.
- proofread neuron: a segment that people have proofread and
joined into a neuron (
proofread_ids). - strength \(s(T \to j)\): the weight of the heaviest single connection from a cell of the type \(T\) onto the partner \(j\).
- strong partner: a proofread partner that is not an LC cell
and has a strength of at least
STRONG_SYN. - two hops: from a type to its strong output partners \(X\), and from them to the cells \(Y\) that they connect to strongly.
- weight \(w(i \to j)\): the number of synapses in the connection from \(i\) to \(j\).